Showing posts with label linux. Show all posts

Tuesday, 23 May 2017

AWS VS OpenStack?????

Let us compare the popularity of two top cloud-computing platforms:
1) the infamous Amazon Web Services, which companies typically leverage for the speed and convenience of Amazon's global, hosted, cloud-computing infrastructure, and
2) the increasingly versatile OpenStack, which allows organizations to roll their own cloud-computing services on standard hardware.

OpenStack has similarly grown in popularity since its launch in 2010, having had a nice jump in the Spring of 2013. Some of the more notable companies contributing to OpenStack include: AT&T, MD, Canonical, Cisco, Citrix, Comcast, Cray, Dell, Dreamhost, EMC, Ericsson, Fujitsu, GoDaddy, Google, HP, Hitachi, Huawei, IBM, Intel, Juniper Networks, Mirantis, Oracle, Red Hat, SUSE Linux, VMware, and Yahoo!.
While OpenStack has a lot of diverse contributors, AWS is the fifth largest web hosting provider globally.
Worldwide Market Share by Number of Clients in 2015:
  1. GoDaddy - 4.26%
  2. BlueHost - 2.56%
  3. Host Gator - 2.15%
  4. OVH.com - 1.91%
  5. Amazon Web Services - 1.81%
  6. Rackspace - 1.59%
  7. 1&1 - 1.54%
  8. Hetzner - 1.29%
  9. SoftLayer - 1.19%
  10. DreamHost - 1.01%

source: http://hostadvice.com/marketshare/ (2015)

As an open-source cloud-computing protocol, OpenStack obviously can't compete on these terms with a multi-billion dollar cloud-computing and software-as-a-service company. There are a number selling points to consider, however:
  • WalMart uses OpenStack to coordinate 100,000+ cores, this provided 100% uptime during Black Friday last year
  • Developers gave over 300 talks at the OpenStack Summit in Tokyo this October
  • Debian, Canonical, Red Hat, and SUSE Linux all support OpenStack and are active contributors
  • OpenStack has enabled companies like Disney, Bloomberg, and Wells Fargo to manage their own clouds at a fraction of the cost of proprietary solutions like AWS
  • OpenStack is the only solution that supports mixed hypervisor and bare metal server environments

I think these points lend themselves to the conclusion that adoption and further development in OpenStack are likely to keep pace.

Here is a subset of AWS services:

In the Compute realm we have...
  • Amazon Elastic Compute Cloud (EC2) scalable virtual private servers using Xen
  • Amazon Elastic MapReduce (EMR) Hadoop-based big data analytics
In Networking we have...
  • Amazon Route 53 scalable DNS
  • Amazon Virtual Private Cloud (VPC) isolated EC2 instances with the ability to extend corporate networks VPN
  • Amazon Elastic Load Balancing (ELB)
In Content Delivery we have...
  • Amazon CloudFront CDN
In Storage we have...
  • Amazon Simple Storage Service (S3)
  • Amazon Glacier low-cost, long-term storage for data archival
  • Amazon Elastic File System (EFS) to accompany EC2
In the Database realm we have...
  • Amazon DynamoDB low-latency NoSQL SSD-backed databases
  • Amazon Relational Database Service (RDS) with MySQL, Oracle, SQL Server, and PostgreSQL support
  • Amazon SimpleDB distributed database with EC2 and S3 interoperability, written in Erlang
In the Deployment realm we have...
  • AWS Elastic Beanstalk for quick deployment and cloud app management
  • AWS OpsWorks EC2 configuration services via Chef, which we discussed previously
In Management we have...
  • Amazon Identity and Access Management (IAM) to authenticate into the various services
  • AWS Directory Service for tying into an on-premises Microsoft Active Directory or for setting up a new stand-alone AWS directory
  • Amazon CloudWatch for application and resource monitoring
  • Amazon CloudHSM Hardware Security Module for data security and for meeting regulatory compliance requirements
  • AWS Key Management Service (KMS) for creating and managing encryption keys
In the Application Services realm we have...
  • Amazon DevPay (beta) for billing and account management
  • Amazon Elastic Transcoder (ETS) for mobile video transcription from S3
  • Amazon Simple Email Service (SES) for sending bulk and transactional email
  • Amazon Simple Notification Service (SNS) multi-protocol application "push" notifications
  • Amazon Cognito secure application-user data management and synchronization tool
In Analytics we have...

Here are the main components of the modular OpenStack architecture:

Compute (Nova)
  • An Infrastructure as a Service (IaaS) system
  • Management and automatation of pools of computer resources
  • Bare metal and high-performance computing (HPC) configurations
  • KVM, VMware, and Xen hypervisor virtualization
  • Hyper-V and LXC containerization
  • Python-based with various external libraries: Eventlet for concurrent programming, Kombu for AMQP communication, SQLAlchemy for database access, etc.
  • Designed to scale horizontally on standard hardware with no proprietary hardware or software requirements
  • Interoperable with legacy systems
Image Service (Glance)
  • OpenStack Image Service for discovery, registration, and delivery of services for disk and server images
  • Template-building from stored images
  • Storage and cataloging of unlimited backups
  • REST interface for querying disk image information
  • Streaming of images to servers
  • VMware integration, with vMotion Dynamic Resource Scheduling (DRS) and live migration of running virtual machines
  • All OpenStack OS images built on virtual machines
  • Maintenance of image metadata
  • Creation, deletion, sharing, and duplification of images
Object Storage (Swift)
  • Scalable redundant storage system
  • Automatic replication of content from failed disks to other active nodes
  • Suitable for inexpensive commodity hard drives and servers
Dashboard (Horizon)
  • GUI for access, provision, and automation of cloud-based resources for administrators and users
  • Third-party billing, monitoring, management tool integration
  • Customizable (brandable) dashboard
  • EC2 compatibility
Identity Service (Keystone)
  • Unified authentication system across the cloud OS
  • Integration with existing backend directory services such as LDAP
  • Various authentication methods: username/password, token-based systems, and AWS-style logins
  • Queryable, single registry of all deployed services, with programmatic determination of access for users and third-party tools
Networking (Neutron)
  • Manual and automatic management of networks and IP addresses
  • Distict networking models for different applications and user groups
  • Flat networks (VLAN's) for separating servers and traffic.
  • Static IP addresses, DHCP
  • Floating IP addresses for dynamic rerouting to resources on the network
  • Software-defined networking (SDN), OpenFlow, for multi-tenancy and scalability.
  • Management of intrusion detection systems (IDS), load balancing, firewalls, VPN's, etc.
Block Storage (Cinder)
  • Persistent block-level storage for databases and expandable file systems
  • Block storage integration into OpenStack Compute and Dashboard for allocation of storage
  • Various storage platforms supported: Ceph, CloudByte, Coraid, EMC (ScaleIO, VMAX and VNX), GlusterFS, Hitachi Data Systems, IBM Storage (Storwize family, SAN Volume Controller, XIV Storage System, and GPFS), Linux LIO, NetApp, Nexenta, Scality, SolidFire, HP (StoreVirtual and 3PAR StoreServ families) and Pure Storag
  • Snapshot management for backing up data stored on block storage volumes
  • Restoring of snapshots, use of snapshots as templates for new block storage volumes
Orchestration (Heat)
  • Orchestratation of multiple composite cloud applications using templates
  • OpenStack-native REST API
  • CloudFormation-compatible Query API
Telemetry (Ceilometer)
  • Billing system Single Point Of Contact
  • Traceable, auditable delivery of counters for billing
  • Counters extensible to new projects
  • Independent data collection
Database (Trove)
  • Database-as-a-service (DaaS) provisioning relational database engine
  • DaaS non-relational database engine
Elastic Map Reduce (Sahara)
  • Hadoop cluster provisioning
  • Setting of parameters based on: Hadoop version, cluster topology, node hardware details, etc.
  • Cluster deployment in minutes
  • Scaling of already-provisioned clusters by adding and removing worker nodes on demand
Bare Metal Provisioning (Ironic)
  • Provisioning of bare metal machines (as opposed to virtual machines)
  • Bare-metal hypervisor API
  • Plugins for interacting with bare-metal hypervisors
  • PXE and IPMI simultaneous provisioning, turning machines on and off as needed
  • Extensible with vendor-specific plugins for additional functionality
Multiple Tenant Cloud Messaging (Zaqar)
  • Multi-tenant cloud messaging service for Web developers
  • Some components inspired by Amazon's SQS, with additional semantics for event broadcasting
  • Fully RESTful API for sending messages between various components of their SaaS and mobile applications
  • Surfacing of events to end users and guest agents that run in the "over-cloud" layer
Shared File System Service (Manila)
  • Vendor-agnostic share management API
  • Create, delete, give/deny access to a share
  • Support for commercial storage appliances from: EMC, NetApp, HP, IBM, Oracle, Quobyte, and Hitachi Data Systems
  • Support for Red Hat's GlusterFS filesystem
DNSaaS (Designate)
  • DNS as a Service
Security API (Barbican)
  • REST API for secure storage, provisioning and management of secrets
  • Built for use in all environments, including large ephemeral clouds
AWS Compatibility

  • Interoperability with Amazon EC2 and Amazon S3
  • Minimal effort to port AWS client applications to OpenStack

Multi tenancy: AWS vs OpenStack

The first conceptual difference between AWS and OpenStack is about multi-tenancy. OpenStack offers a multi-layer tenant mechanism with domain and projects. A domain is a collection of users, groups, and projects, in a way parallel to AWS’s account. LDAP groups are attached to domains. OpenStack’s Project is a container of virtual resources such as virtual machines, networks and volumes. Using projects, users can establish several isolated and independently controlled groups of resources that serve different objectives. In the Kilo release, Keystone introduced the hierarchical multi-tenancy concept, using sub-projects.
Accommodating more than one million customers, Amazon Web Services is a multi-tenant cloud by nature; however, at the account level, a single user receives a single tenant experience. Having said that, AWS offers Virtual Private Cloud, VPC, which is somewhat parallel to OpenStack’s project. Amazon’s VPC lets the user provision a logically isolated section of the Amazon Web Services (AWS) cloud where the user can launch AWS resources in a virtual network that s/he defines.  AWS’s VPC is limited to one router and one IP block; though not compulsory, this is a common practice for OpenStack projects. It is worth noting that all EC2’s virtual networking capabilities are only available using VPC.
On the other hand, unlike OpenStack, Amazon’s VPC offers extremely valuable tools that simplify the establishment of secured connectivity between VPCs and between VPC and on-premise resources. The classical use case for enterprises is running the web servers or the entire customer facing application on Amazon’s public cloud, while keeping the rest of the servers on-premise. Through its API, Amazon allows the user to establish a VPN connection and even control the customer’s and AWS’s gateways. This is extremely valuable for enterprises that chose the hybrid cloud path, especially given the fact that Amazon has integrated its VPN gateway with the market leading VPN CPEs (customer premise equipment). OpenStack’s Neutron project does offers VPN as a Service capabilities (VPNaaS); however, it is experimental and lacks the end-to-end integration that Amazon provides.

Networking: Neutron vs AWS VPC

From the network perspective, while OpenStack provides control over the L2 elements of the virtual network, AWS exposes only subnets. OpenStack Neutron’s API allows granular control of elements such as ports (the connection point for attaching a virtual server to a virtual network) and the ability to allocate VLAN IDs that correspond to VLANs present in the physical network. This is especially useful for provider networks, which are mapped to existing physical networks in the data center. Those differences are again attributed to the different concepts of AWS and OpenStack. In the private cloud, the user manages the physical networking by himself. Thus, it is crucial for virtual networking to be fully integrated with the physical data center networking. However, the public cloud is a managed service that takes all the hassle of physical network management away from the user, therefore  providing control on L2 is irrelevant to the user.
As for Layer 3 networking, conceptually, Amazon’s AWS and OpenStack’s Neutron provides comparable capabilities. Both cloud services allow creation of network subnets. OpenStack allows use of several subnets on the same virtual network, although it is not a common practice. AWS allows users to define Elastic IP addresses, which are public IP addresses reachable from the Internet. OpenStack offers a similar mechanism, the floating IP, which is part of the virtual router’s API.
Both clouds provide routing services; in AWS each VPC includes an implicit virtual router and the API allows the user to set the routing table (which contains a set of rules, called routes, that are used to determine where network traffic is directed). OpenStack’s Neutron API also allows management of the routing table;  however, it also allows management of the router entities themselves and does not limiting the number of routers per project. Moreover, a single router can be connected to more than one project.
From a network security perspective, AWS and OpenStack offer similar mechanisms. Security groups are used to inspect the traffic at the instance level. Networking ACLs and virtual firewalls are used by AWS and OpenStack respectively to inspect traffic going between subnets. There are minor nuances unique to each API; however, the general concept is very similar.

Here we compare some main components of AWS and OpenStack

Compute

 Why you need it?

To run an application you need a server with CPU, memory and storage, with or without pre-installed operating systems and applications.
OpenStack
AWS
Definition
Compute is virtual machines/servers
Instance
Instance/VM
Sizes
How much memory and CPU and temporary (ephemeral) storage is assigned to the instances/VM.
Flavors: Variety of sizes: micro, small, medium, large etc.
Variety of sizes: micro, small, medium, large etc.
Operating systems offered
What operating systems does the cloud offer to end-users
Whatever operating systems the cloud administrators host on the OpenStack cloud. (Red Hat certifies Microsoft Windows, RHEL and SUSE)
AMIs provided by the AWS marketplace.
Templates/images
A base configuration of a virtual machine, from which other virtual machines can be created.
Catalogs of virtual machine images can be created from which users can select a virtual machine.
Glance 
OpenStack administrators upload images and create catalogs for users.
Users can upload their own images.
(AMI) Amazon Machine Image
AWS provides an online marketplace of pre-defined images.
Users can upload their own images.

Networking

 Why you need it?
To network virtual servers to each other. You also need to control who can access the server. You want to protect/firewall the server especially if it is exposed to the Internet.
OpenStack
AWS
Definition
Networking provides connectivity for users to virtual machines. Connects virtual machines to one another and to external networks (the Internet).  
Neutron
Networking
A private IP address internal only and non-routable to the Internet
Every virtual instance is automatically assigned a private IP address, typically using DHCP.
AWS allocates a private IP address for the instance using DHCP.
Public IP address
A floating IP is a public IP address, that you can dynamically add to a running virtual instance.
AWS public IP address is mapped to the primary private IP address.
Networking service
You can create networks and networking functions, eg. L3 forwarding, NAT, edge firewalls, and IPsec VPN.
Virtual routers or switches can be added if you use AWS VPC, a virtual public cloud.
Load Balance VM traffic
OpenStack LBaaS (Load Balancing as a Service) balances traffic from one network to application services.
ELB (Elastic Load Balancing) automatically distributes incoming application traffic across Amazon EC2 instances.
DNS.
Manage the DNS entries for your virtual servers and web applications.
The OpenStack DNS project (Designate) is in “incubation” and is not part of core OpenStack (as of the April 2015 Kilo release).
Route 53 –  AWS’s DNS service.
SRIOV
A method of device virtualization that provides higher I/O performance and lower CPU utilization compared to traditional implementations.
Each SR-IOV port is associated with a virtual function (VF). SR-IOV ports may be provided by Hardware-based Virtual Ethernet Bridging or they may be extended to an upstream physical switch (IEEE 802.1br).
AWS support enhanced networking capabilities using SR-IOV, provides higher packet per second (PPS) performance, lower inter-instance latencies, and very low network jitter.

Monitoring

Why you need it?

You get insight into usage patterns and utilization of the physical and virtual resources. You may want to account for individual usage and optionally bill users for their usage.
OpenStack
AWS
Definition
Monitoring provides metering and usage of the cloud.  
Ceilometer
Cloudwatch
System-wide metering and usage.
Option to bill users for their usage
To collect measurements of the utilization of the physical and virtual resources comprising deployed clouds.
Persist data for subsequent retrieval and analysis, and trigger actions when defined criteria are met.
Monitoring service for AWS cloud resources and the applications  on AWS.
Collect and track metrics, collect and monitor log files, and set alarms.

Security

Why you need it?

You need the  option of public key cryptography for SSH and password decryption. You want to firewall virtual machines to only allow certain traffic in (ingress) or out (egress).


OpenStack
AWS
Definition
Control access to your virtual machines.  
Keypairs, security groups.
Key pairs
To login to your VM or instance, you must create a key pair.
Linux: used to SSH.
Windows: used to decrypt the Administrator password.
When you launch a virtual machine, you can inject a key pair, which provides SSH access to your instance.
To log in to your instance, specify the name of the key pair when you launch the instance, and provide the private key when you connect to the instance.
Assign and control access to VM instances.
A security group is a named collection of network access rules that limit the traffic that access an instance.
When you launch an instance, you can assign one or more security groups to it.
Supported
Supported

Friday, 19 May 2017

Intro to NFV???

Network function virtualization (NFV) also known as virtual network function (VNF)) offers a new way to design, deploy and manage networking services. NFV decouples the network functions, such as network address translation (NAT), firewalling, intrusion detection, domain name service (DNS), and caching, to name a few, from proprietary hardware appliances so they can run in software.
It’s designed to consolidate and deliver the networking components needed to support a fully virtualized infrastructure – including virtual servers, storage, and even other networks. It utilizes standard IT virtualization technologies that run on high-volume service, switch and storage hardware to virtualize network functions. It is applicable to any data plane processing or control plane function in both wired and wireless network infrastructures.

How a Managed Router Service Can be Deployed with NFV

Example of a Managed Router Service would be Deployed with Network Functions Virtualization NFV
Sample Network Functions Virtualization NFV deployment

Background


Product development within the telecommunication industry has traditionally followed rigorous standards for stability, protocol adherence and quality, reflected by the use of the term carrier grade to designate equipment demonstrating this reliability.While this model worked well in the past, it inevitably led to long product cycles, a slow pace of development and reliance on proprietary or specific hardware, e.g., bespoke application-specific integrated circuits (ASICs). The rise of significant competition in communication services from fast-moving organizations operating at large scale on the public Internet (such as Google Talk, Skype, Netflix) has spurred service providers to look for ways to disrupt the status quo.

History of Network Functions Virtualization

The concept originated from service providers who were looking to accelerate the deployment of new network services to support their revenue and growth objectives. The constraints of hardware-based appliances led them to applying standard IT virtualization technologies to their networks. To accelerate progress towards this common goal, several providers came together and created the European Telecommunications Standards Institute (ETSI).
The ETSI Industry Specification Group for Network Functions Virtualization (ETSI ISG NFV), a group charged with developing requirements and architecture for virtualization for various functions within telecoms networks, such as standards like NFV MANO. ETSI is also instrumental in collaborative projects like the newly announced OPNFV.

NFV Framework

The NFV framework consists of three main components:
  1. Virtualized network functions (VNFs) are software implementations of network functions that can be deployed on a network functions virtualization infrastructure (NFVI).
  2. Network functions virtualization infrastructure (NFVI) is the totality of all hardware and software components that build the environment where VNFs are deployed. The NFV infrastructure can span several locations. The network providing connectivity between these locations is considered as part of the NFV infrastructure.
  3. Network functions virtualization management and orchestration architectural framework (NFV-MANO Architectural Framework) is the collection of all functional blocks, data repositories used by these blocks, and reference points and interfaces through which these functional blocks exchange information for the purpose of managing and orchestrating NFVI and VNFs.

The building block for both the NFVI and the NFV-MANO is the NFV platform. In the NFVI role, it consists of both virtual and physical processing and storage resources, and virtualization software. In its NFV-MANO role it consists of VNF and NFVI managers and virtualization software operating on a hardware controller. The NFV platform implements carrier-grade features used to manage and monitor the platform components, recover from failures and provide effective security - all required for the public carrier network.

The Benefits of Network Functions Virtualization

NFV virtualizes network services via software to enable operators to:

  • Reduce CapEx: reducing the need to purchase purpose-built hardware and supporting pay-as-you-grow models to eliminate wasteful over-provisioning.
  • Reduce OpEX: reducing space, power and cooling requirements of equipment and simplifying the roll out and management of network services.
  • Accelerate Time-to-Market: reducing the time to deploy new networking services to support changing business requirements, seize new market opportunities and improve return on investment of new services. Also lowers the risks associated with rolling out new services, allowing providers to easily trial and evolve services to determine what best meets the needs of customers.
  • Deliver Agility and Flexibility: quickly scale up or down services to address changing demands; support innovation by enabling services to be delivered via software on any industry-standard server hardware.

Distributed NFV

The initial perception of NFV was that virtualized capability should be implemented in data centers. This approach works in many – but not all – cases. NFV presumes and emphasizes the widest possible flexibility as to the physical location of the virtualized functions.
Ideally, therefore, virtualized functions should be located where they are the most effective and least expensive. That means a service provider should be free to locate NFV in all possible locations, from the data center to the network node to the customer premises. This approach, known as distributed NFV, has been emphasized from the beginning as NFV was being developed and standardized, and is prominent in the recently released NFV ISG documents.
For some cases there are clear advantages for a service provider to locate this virtualized functionality at the customer premises. These advantages range from economics to performance to the feasibility of the functions being virtualized.
The first ETSI NFV ISG-approved public multi-vendor proof of concept (PoC) of D-NFV was conducted by Cyan, Inc., RAD, Fortinet and Certes Networks in Chicago in June, 2014, and was sponsored by CenturyLink. It was based on RAD’s dedicated customer-edge D-NFV equipment running Fortinet’s Next Generation Firewall (NGFW) and Certes Networks’ virtual encryption/decryption engine as Virtual Network Functions (VNFs) with Cyan’s Blue Planet system orchestrating the entire ecosystem. RAD's D-NFV solution, a Layer 2/Layer 3 network termination unit (NTU) equipped with a D-NFV X86 server module that functions as a virtualization engine at the customer edge, became commercially available by the end of that month. During 2014 RAD also had organized a D-NFV Alliance, an ecosystem of vendors and international systems integrators specializing in new NFV applications.

In our next blogs we discuss SDN and also what is difference between NFV and SDN. Keep reading and follow blog.

Monday, 24 April 2017

Intro to Redis

Introduction to Redis


Redis is an open source (BSD licensed), in-memory data structure store, used as a database, cache and message broker. It supports data structures such as strings, hashes, lists, sets, sorted sets with range queries, bitmaps, hyperlog logs and geospatial indexes with radius queries. Redis has built-in replication, Lua scripting, LRU eviction, transactions and different levels of on-disk persistence, and provides high availability via Redis Sentinel and automatic partitioning with Redis Cluster.

You can run atomic operations on these types, like appending to a string; incrementing the value in a hash; pushing an element to a list; computing set intersection, union and difference; or getting the member with highest ranking in a sorted set.

In order to achieve its outstanding performance, Redis works with an in-memory data set. Depending on your use case, you can persist it either by dumping the data set to disk every once in a while, or by appending each command to a log. Persistence can be optionally disabled, if you just need a feature-rich, networked, in-memory cache.

Redis also supports trivial-to-setup master-slave asynchronous replication, with very fast non-blocking first synchronization, auto-re-connection with partial re-synchronization on net split.

Other features include:


  •     Transactions
  •     Pub/Sub
  •     Lua scripting
  •     Keys with a limited time-to-live
  •     LRU eviction of keys
  •     Automatic fail over


You can use Redis from most programming languages out there.

Redis is written in ANSI C and works in most POSIX systems like Linux, *BSD, OS X without external dependencies. Linux and OS X are the two operating systems where Redis is developed and more tested, and we recommend using Linux for deploying. Redis may work in Solaris-derived systems like SmartOS, but the support is best effort. There is no official support for Windows builds, but Microsoft develops and maintains a Win-64 port of Redis.

An introduction to Redis data types and abstractions

Redis is not a plain key-value store, it is actually a data structures server, supporting different kinds of values. What this means is that, while in traditional key-value stores you associated string keys to string values, in Redis the value is not limited to a simple string, but can also hold more complex data structures. The following is the list of all the data structures supported by Redis, which will be covered separately in this tutorial:
  • Binary-safe strings.
  • Lists: collections of string elements sorted according to the order of insertion. They are basically linked lists.
  • Sets: collections of unique, unsorted string elements.
  • Sorted sets, similar to Sets but where every string element is associated to a floating number value, called score. The elements are always taken sorted by their score, so unlike Sets it is possible to retrieve a range of elements (for example you may ask: give me the top 10, or the bottom 10).
  • Hashes, which are maps composed of fields associated with values. Both the field and the value are strings. This is very similar to Ruby or Python hashes.
  • Bit arrays (or simply bitmaps): it is possible, using special commands, to handle String values like an array of bits: you can set and clear individual bits, count all the bits set to 1, find the first set or unset bit, and so forth.
  • HyperLogLogs: this is a probabilistic data structure which is used in order to estimate the cardinality of a set. Don't be scared, it is simpler than it seems... See later in the HyperLogLog section of this tutorial.
It's not always trivial to grasp how these data types work and what to use in order to solve a given problem from the command reference, so this document is a crash course to Redis data types and their most common patterns.
For all the examples we'll use the redis-cli utility, a simple but handy command-line utility, to issue commands against the Redis server.

Redis keys

Redis keys are binary safe, this means that you can use any binary sequence as a key, from a string like "foo" to the content of a JPEG file. The empty string is also a valid key.
A few other rules about keys:
  • Very long keys are not a good idea. For instance a key of 1024 bytes is a bad idea not only memory-wise, but also because the lookup of the key in the dataset may require several costly key-comparisons. Even when the task at hand is to match the existence of a large value, hashing it (for example with SHA1) is a better idea, especially from the perspective of memory and bandwidth.
  • Very short keys are often not a good idea. There is little point in writing "u1000flw" as a key if you can instead write "user:1000:followers". The latter is more readable and the added space is minor compared to the space used by the key object itself and the value object. While short keys will obviously consume a bit less memory, your job is to find the right balance.
  • Try to stick with a schema. For instance "object-type:id" is a good idea, as in "user:1000". Dots or dashes are often used for multi-word fields, as in "comment:1234:reply.to" or "comment:1234:reply-to".
  • The maximum allowed key size is 512 MB.

Redis Strings

The Redis String type is the simplest type of value you can associate with a Redis key. It is the only data type in Memcached, so it is also very natural for newcomers to use it in Redis.
Since Redis keys are strings, when we use the string type as a value too, we are mapping a string to another string. The string data type is useful for a number of use cases, like caching HTML fragments or pages.
Let's play a bit with the string type, using redis-cli (all the examples will be performed via redis-cli in this tutorial).
> set mykey somevalue
OK
> get mykey
"somevalue"
As you can see using the SET and the GET commands are the way we set and retrieve a string value. Note that SET will replace any existing value already stored into the key, in the case that the key already exists, even if the key is associated with a non-string value. So SET performs an assignment.
Values can be strings (including binary data) of every kind, for instance you can store a jpeg image inside a key. A value can't be bigger than 512 MB.
The SET command has interesting options, that are provided as additional arguments. For example, I may ask SET to fail if the key already exists, or the opposite, that it only succeed if the key already exists:
> set mykey newval nx
(nil)
> set mykey newval xx
OK
Even if strings are the basic values of Redis, there are interesting operations you can perform with them. For instance, one is atomic increment:
> set counter 100
OK
> incr counter
(integer) 101
> incr counter
(integer) 102
> incrby counter 50
(integer) 152
The INCR command parses the string value as an integer, increments it by one, and finally sets the obtained value as the new value. There are other similar commands like INCRBY, DECR and DECRBY. Internally it's always the same command, acting in a slightly different way.
What does it mean that INCR is atomic? That even multiple clients issuing INCR against the same key will never enter into a race condition. For instance, it will never happen that client 1 reads "10", client 2 reads "10" at the same time, both increment to 11, and set the new value to 11. The final value will always be 12 and the read-increment-set operation is performed while all the other clients are not executing a command at the same time.
There are a number of commands for operating on strings. For example the GETSET command sets a key to a new value, returning the old value as the result. You can use this command, for example, if you have a system that increments a Redis key using INCR every time your web site receives a new visitor. You may want to collect this information once every hour, without losing a single increment. You can GETSET the key, assigning it the new value of "0" and reading the old value back.
The ability to set or retrieve the value of multiple keys in a single command is also useful for reduced latency. For this reason there are the MSET and MGET commands:
> mset a 10 b 20 c 30
OK
> mget a b c
1) "10"
2) "20"
3) "30"
When MGET is used, Redis returns an array of values.

Altering and querying the key space

There are commands that are not defined on particular types, but are useful in order to interact with the space of keys, and thus, can be used with keys of any type.
For example the EXISTS command returns 1 or 0 to signal if a given key exists or not in the database, while the DEL command deletes a key and associated value, whatever the value is.
> set mykey hello
OK
> exists mykey
(integer) 1
> del mykey
(integer) 1
> exists mykey
(integer) 0
From the examples you can also see how DEL itself returns 1 or 0 depending on whether the key was removed (it existed) or not (there was no such key with that name).
There are many key space related commands, but the above two are the essential ones together with the TYPE command, which returns the kind of value stored at the specified key:
> set mykey x
OK
> type mykey
string
> del mykey
(integer) 1
> type mykey
none

Redis expires: keys with limited time to live

Before continuing with more complex data structures, we need to discuss another feature which works regardless of the value type, and is called Redis expires. Basically you can set a timeout for a key, which is a limited time to live. When the time to live elapses, the key is automatically destroyed, exactly as if the user called the DEL command with the key.
A few quick info about Redis expires:
  • They can be set both using seconds or milliseconds precision.
  • However the expire time resolution is always 1 millisecond.
  • Information about expires are replicated and persisted on disk, the time virtually passes when your Redis server remains stopped (this means that Redis saves the date at which a key will expire).
Setting an expire is trivial:
> set key some-value
OK
> expire key 5
(integer) 1
> get key (immediately)
"some-value"
> get key (after some time)
(nil)
The key vanished between the two GET calls, since the second call was delayed more than 5 seconds. In the example above we used EXPIRE in order to set the expire (it can also be used in order to set a different expire to a key already having one, like PERSIST can be used in order to remove the expire and make the key persistent forever). However we can also create keys with expires using other Redis commands. For example using SET options:
> set key 100 ex 10
OK
> ttl key
(integer) 9
The example above sets a key with the string value 100, having an expire of ten seconds. Later the TTL command is called in order to check the remaining time to live for the key.
In order to set and check expires in milliseconds, check the PEXPIRE and the PTTL commands, and the full list of SET options.

Redis Lists

To explain the List data type it's better to start with a little bit of theory, as the term List is often used in an improper way by information technology folks. For instance "Python Lists" are not what the name may suggest (Linked Lists), but rather Arrays (the same data type is called Array in Ruby actually).
From a very general point of view a List is just a sequence of ordered elements: 10,20,1,2,3 is a list. But the properties of a List implemented using an Array are very different from the properties of a List implemented using a Linked List.
Redis lists are implemented via Linked Lists. This means that even if you have millions of elements inside a list, the operation of adding a new element in the head or in the tail of the list is performed in constant time. The speed of adding a new element with the LPUSH command to the head of a list with ten elements is the same as adding an element to the head of list with 10 million elements.
What's the downside? Accessing an element by index is very fast in lists implemented with an Array (constant time indexed access) and not so fast in lists implemented by linked lists (where the operation requires an amount of work proportional to the index of the accessed element).
Redis Lists are implemented with linked lists because for a database system it is crucial to be able to add elements to a very long list in a very fast way. Another strong advantage, as you'll see in a moment, is that Redis Lists can be taken at constant length in constant time.
When fast access to the middle of a large collection of elements is important, there is a different data structure that can be used, called sorted sets. Sorted sets will be covered later in this tutorial.

First steps with Redis Lists

The LPUSH command adds a new element into a list, on the left (at the head), while the RPUSH command adds a new element into a list ,on the right (at the tail). Finally the LRANGE command extracts ranges of elements from lists:
> rpush mylist A
(integer) 1
> rpush mylist B
(integer) 2
> lpush mylist first
(integer) 3
> lrange mylist 0 -1
1) "first"
2) "A"
3) "B"
Note that LRANGE takes two indexes, the first and the last element of the range to return. Both the indexes can be negative, telling Redis to start counting from the end: so -1 is the last element, -2 is the penultimate element of the list, and so forth.
As you can see RPUSH appended the elements on the right of the list, while the final LPUSH appended the element on the left.
Both commands are variadic commands, meaning that you are free to push multiple elements into a list in a single call:
> rpush mylist 1 2 3 4 5 "foo bar"
(integer) 9
> lrange mylist 0 -1
1) "first"
2) "A"
3) "B"
4) "1"
5) "2"
6) "3"
7) "4"
8) "5"
9) "foo bar"
An important operation defined on Redis lists is the ability to pop elements. Popping elements is the operation of both retrieving the element from the list, and eliminating it from the list, at the same time. You can pop elements from left and right, similarly to how you can push elements in both sides of the list:
> rpush mylist a b c
(integer) 3
> rpop mylist
"c"
> rpop mylist
"b"
> rpop mylist
"a"
We added three elements and popped three elements, so at the end of this sequence of commands the list is empty and there are no more elements to pop. If we try to pop yet another element, this is the result we get:
> rpop mylist
(nil)
Redis returned a NULL value to signal that there are no elements into the list.

Common use cases for lists

Lists are useful for a number of tasks, two very representative use cases are the following:
  • Remember the latest updates posted by users into a social network.
  • Communication between processes, using a consumer-producer pattern where the producer pushes items into a list, and a consumer (usually a worker) consumes those items and executed actions. Redis has special list commands to make this use case both more reliable and efficient.
For example both the popular Ruby libraries resque and sidekiq use Redis lists under the hood in order to implement background jobs.
The popular Twitter social network takes the latest tweets posted by users into Redis lists.
To describe a common use case step by step, imagine your home page shows the latest photos published in a photo sharing social network and you want to speedup access.
  • Every time a user posts a new photo, we add its ID into a list with LPUSH.
  • When users visit the home page, we use LRANGE 0 9 in order to get the latest 10 posted items.

Capped lists

In many use cases we just want to use lists to store the latest items, whatever they are: social network updates, logs, or anything else.
Redis allows us to use lists as a capped collection, only remembering the latest N items and discarding all the oldest items using the LTRIM command.
The LTRIM command is similar to LRANGE, but instead of displaying the specified range of elements it sets this range as the new list value. All the elements outside the given range are removed.
An example will make it more clear:
> rpush mylist 1 2 3 4 5
(integer) 5
> ltrim mylist 0 2
OK
> lrange mylist 0 -1
1) "1"
2) "2"
3) "3"
The above LTRIM command tells Redis to take just list elements from index 0 to 2, everything else will be discarded. This allows for a very simple but useful pattern: doing a List push operation + a List trim operation together in order to add a new element and discard elements exceeding a limit:
LPUSH mylist 
LTRIM mylist 0 999
The above combination adds a new element and takes only the 1000 newest elements into the list. With LRANGE you can access the top items without any need to remember very old data.

Note: while LRANGE is technically an O(N) command, accessing small ranges towards the head or the tail of the list is a constant time operation.

Automatic creation and removal of keys

So far in our examples we never had to create empty lists before pushing elements, or removing empty lists when they no longer have elements inside. It is Redis' responsibility to delete keys when lists are left empty, or to create an empty list if the key does not exist and we are trying to add elements to it, for example, with LPUSH.
This is not specific to lists, it applies to all the Redis data types composed of multiple elements -- Sets, Sorted Sets and Hashes.
Basically we can summarize the behavior with three rules:
  1. When we add an element to an aggregate data type, if the target key does not exist, an empty aggregate data type is created before adding the element.
  2. When we remove elements from an aggregate data type, if the value remains empty, the key is automatically destroyed.
  3. Calling a read-only command such as LLEN (which returns the length of the list), or a write command removing elements, with an empty key, always produces the same result as if the key is holding an empty aggregate type of the type the command expects to find.
Examples of rule 1:
> del mylist
(integer) 1
> lpush mylist 1 2 3
(integer) 3
However we can't perform operations against the wrong type if the key exists:
> set foo bar
OK
> lpush foo 1 2 3
(error) WRONGTYPE Operation against a key holding the wrong kind of value
> type foo
string
Example of rule 2:
> lpush mylist 1 2 3
(integer) 3
> exists mylist
(integer) 1
> lpop mylist
"3"
> lpop mylist
"2"
> lpop mylist
"1"
> exists mylist
(integer) 0
The key no longer exists after all the elements are popped.
Example of rule 3:
> del mylist
(integer) 0
> llen mylist
(integer) 0
> lpop mylist
(nil)

Redis Hashes

Redis hashes look exactly how one might expect a "hash" to look, with field-value pairs:
> hmset user:1000 username antirez birthyear 1977 verified 1
OK
> hget user:1000 username
"antirez"
> hget user:1000 birthyear
"1977"
> hgetall user:1000
1) "username"
2) "antirez"
3) "birthyear"
4) "1977"
5) "verified"
6) "1"
While hashes are handy to represent objects, actually the number of fields you can put inside a hash has no practical limits (other than available memory), so you can use hashes in many different ways inside your application.
The command HMSET sets multiple fields of the hash, while HGET retrieves a single field. HMGET is similar to HGET but returns an array of values:
> hmget user:1000 username birthyear no-such-field
1) "antirez"
2) "1977"
3) (nil)
There are commands that are able to perform operations on individual fields as well, like HINCRBY:
> hincrby user:1000 birthyear 10
(integer) 1987
> hincrby user:1000 birthyear 10
(integer) 1997
You can find the full list of hash commands in the documentation.
It is worth noting that small hashes (i.e., a few elements with small values) are encoded in special way in memory that make them very memory efficient.

Redis Sets

Redis Sets are unordered collections of strings. The SADD command adds new elements to a set. It's also possible to do a number of other operations against sets like testing if a given element already exists, performing the intersection, union or difference between multiple sets, and so forth.
> sadd myset 1 2 3
(integer) 3
> smembers myset
1. 3
2. 1
3. 2
Here I've added three elements to my set and told Redis to return all the elements. As you can see they are not sorted -- Redis is free to return the elements in any order at every call, since there is no contract with the user about element ordering.
Redis has commands to test for membership. For example, checking if an element exists:
> sismember myset 3
(integer) 1
> sismember myset 30
(integer) 0
"3" is a member of the set, while "30" is not.
Sets are good for expressing relations between objects. For instance we can easily use sets in order to implement tags.
A simple way to model this problem is to have a set for every object we want to tag. The set contains the IDs of the tags associated with the object.
One illustration is tagging news articles. If article ID 1000 is tagged with tags 1, 2, 5 and 77, a set can associate these tag IDs with the news item:
> sadd news:1000:tags 1 2 5 77
(integer) 4
We may also want to have the inverse relation as well: the list of all the news tagged with a given tag:
> sadd tag:1:news 1000
(integer) 1
> sadd tag:2:news 1000
(integer) 1
> sadd tag:5:news 1000
(integer) 1
> sadd tag:77:news 1000
(integer) 1
To get all the tags for a given object is trivial:
> smembers news:1000:tags
1. 5
2. 1
3. 77
4. 2
Note: in the example we assume you have another data structure, for example a Redis hash, which maps tag IDs to tag names.
There are other non trivial operations that are still easy to implement using the right Redis commands. For instance we may want a list of all the objects with the tags 1, 2, 10, and 27 together. We can do this using the SINTER command, which performs the intersection between different sets. We can use:
> sinter tag:1:news tag:2:news tag:10:news tag:27:news
... results here ...
In addition to intersection you can also perform unions, difference, extract a random element, and so forth.
The command to extract an element is called SPOP, and is handy to model certain problems. For example in order to implement a web-based poker game, you may want to represent your deck with a set. Imagine we use a one-char prefix for (C)lubs, (D)iamonds, (H)earts, (S)pades:
>  sadd deck C1 C2 C3 C4 C5 C6 C7 C8 C9 C10 CJ CQ CK
   D1 D2 D3 D4 D5 D6 D7 D8 D9 D10 DJ DQ DK H1 H2 H3
   H4 H5 H6 H7 H8 H9 H10 HJ HQ HK S1 S2 S3 S4 S5 S6
   S7 S8 S9 S10 SJ SQ SK
   (integer) 52
Now we want to provide each player with 5 cards. The SPOP command removes a random element, returning it to the client, so it is the perfect operation in this case.
However if we call it against our deck directly, in the next play of the game we'll need to populate the deck of cards again, which may not be ideal. So to start, we can make a copy of the set stored in the deck key into the game:1:deck key.
This is accomplished using SUNIONSTORE, which normally performs the union between multiple sets, and stores the result into another set. However, since the union of a single set is itself, I can copy my deck with:
> sunionstore game:1:deck deck
(integer) 52
Now I'm ready to provide the first player with five cards:
> spop game:1:deck
"C6"
> spop game:1:deck
"CQ"
> spop game:1:deck
"D1"
> spop game:1:deck
"CJ"
> spop game:1:deck
"SJ"
One pair of jacks, not great...
This is a good time to introduce the set command that provides the number of elements inside a set. This is often called the cardinality of a set in the context of set theory, so the Redis command is called SCARD.
> scard game:1:deck
(integer) 47
The math works: 52 - 5 = 47.
When you need to just get random elements without removing them from the set, there is the SRANDMEMBER command suitable for the task. It also features the ability to return both repeating and non-repeating elements.

Redis Sorted sets

Sorted sets are a data type which is similar to a mix between a Set and a Hash. Like sets, sorted sets are composed of unique, non-repeating string elements, so in some sense a sorted set is a set as well.
However while elements inside sets are not ordered, every element in a sorted set is associated with a floating point value, called the score (this is why the type is also similar to a hash, since every element is mapped to a value).
Moreover, elements in a sorted sets are taken in order (so they are not ordered on request, order is a peculiarity of the data structure used to represent sorted sets). They are ordered according to the following rule:
  • If A and B are two elements with a different score, then A > B if A.score is > B.score.
  • If A and B have exactly the same score, then A > B if the A string is lexicographically greater than the B string. A and B strings can't be equal since sorted sets only have unique elements.
Let's start with a simple example, adding a few selected hackers names as sorted set elements, with their year of birth as "score".
> zadd hackers 1940 "Alan Kay"
(integer) 1
> zadd hackers 1957 "Sophie Wilson"
(integer) 1
> zadd hackers 1953 "Richard Stallman"
(integer) 1
> zadd hackers 1949 "Anita Borg"
(integer) 1
> zadd hackers 1965 "Yukihiro Matsumoto"
(integer) 1
> zadd hackers 1914 "Hedy Lamarr"
(integer) 1
> zadd hackers 1916 "Claude Shannon"
(integer) 1
> zadd hackers 1969 "Linus Torvalds"
(integer) 1
> zadd hackers 1912 "Alan Turing"
(integer) 1
As you can see ZADD is similar to SADD, but takes one additional argument (placed before the element to be added) which is the score. ZADD is also variadic, so you are free to specify multiple score-value pairs, even if this is not used in the example above.
With sorted sets it is trivial to return a list of hackers sorted by their birth year because actually they are already sorted.
Implementation note: Sorted sets are implemented via a dual-ported data structure containing both a skip list and a hash table, so every time we add an element Redis performs an O(log(N)) operation. That's good, but when we ask for sorted elements Redis does not have to do any work at all, it's already all sorted:
> zrange hackers 0 -1
1) "Alan Turing"
2) "Hedy Lamarr"
3) "Claude Shannon"
4) "Alan Kay"
5) "Anita Borg"
6) "Richard Stallman"
7) "Sophie Wilson"
8) "Yukihiro Matsumoto"
9) "Linus Torvalds"
Note: 0 and -1 means from element index 0 to the last element (-1 works here just as it does in the case of the LRANGE command).
What if I want to order them the opposite way, youngest to oldest? Use ZREVRANGE instead of ZRANGE:
> zrevrange hackers 0 -1
1) "Linus Torvalds"
2) "Yukihiro Matsumoto"
3) "Sophie Wilson"
4) "Richard Stallman"
5) "Anita Borg"
6) "Alan Kay"
7) "Claude Shannon"
8) "Hedy Lamarr"
9) "Alan Turing"
It is possible to return scores as well, using the WITHSCORES argument:

> zrange hackers 0 -1 withscores
1) "Alan Turing"
2) "1912"
3) "Hedy Lamarr"
4) "1914"
5) "Claude Shannon"
6) "1916"
7) "Alan Kay"
8) "1940"
9) "Anita Borg"
10) "1949"
11) "Richard Stallman"
12) "1953"
13) "Sophie Wilson"
14) "1957"
15) "Yukihiro Matsumoto"
16) "1965"
17) "Linus Torvalds"
18) "1969"

Sunday, 23 April 2017

Kafka using Python

Python client for the Apache Kafka distributed stream processing system. kafka-python is designed to function much like the official java client, with a sprinkling of pythonic interfaces (e.g., consumer iterators).
kafka-python is best used with newer brokers (0.10 or 0.9), but is backwards-compatible with older versions (to 0.8.0). Some features will only be enabled on newer brokers, however; for example, fully coordinated consumer groups – i.e., dynamic partition assignment to multiple consumers in the same group – requires use of 0.9+ kafka brokers. Supporting this feature for earlier broker releases would require writing and maintaining custom leadership election and membership / health check code (perhaps using zookeeper or consul). For older brokers, you can achieve something similar by manually assigning different partitions to each consumer instance with config management tools like chef, ansible, etc. This approach will work fine, though it does not support rebalancing on failures.
Please note that the master branch may contain unreleased features. For release documentation, please see readthedocs and/or python’s inline help.
>>> pip install kafka-python

KafkaConsumer

KafkaConsumer is a high-level message consumer, intended to operate as similarly as possible to the official java client. Full support for coordinated consumer groups requires use of kafka brokers that support the Group APIs: kafka v0.9+.
The consumer iterator returns ConsumerRecords, which are simple namedtuples that expose basic message attributes: topic, partition, offset, key, and value:
>>> from kafka import KafkaConsumer
>>> consumer = KafkaConsumer('my_favorite_topic')
>>> for msg in consumer:
...     print (msg)
>>> # join a consumer group for dynamic partition assignment and offset commits
>>> from kafka import KafkaConsumer
>>> consumer = KafkaConsumer('my_favorite_topic', group_id='my_favorite_group')
>>> for msg in consumer:
...     print (msg)
>>> # manually assign the partition list for the consumer
>>> from kafka import TopicPartition
>>> consumer = KafkaConsumer(bootstrap_servers='localhost:1234')
>>> consumer.assign([TopicPartition('foobar', 2)])
>>> msg = next(consumer)
>>> # Deserialize msgpack-encoded values
>>> consumer = KafkaConsumer(value_deserializer=msgpack.loads)
>>> consumer.subscribe(['msgpackfoo'])
>>> for msg in consumer:
...     assert isinstance(msg.value, dict)

KafkaProducer

KafkaProducer is a high-level, asynchronous message producer. The class is intended to operate as similarly as possible to the official java client
>>> from kafka import KafkaProducer
>>> producer = KafkaProducer(bootstrap_servers='localhost:1234')
>>> for _ in range(100):
...     producer.send('foobar', b'some_message_bytes')
>>> # Block until a single message is sent (or timeout)
>>> future = producer.send('foobar', b'another_message')
>>> result = future.get(timeout=60)
>>> # Block until all pending messages are at least put on the network
>>> # NOTE: This does not guarantee delivery or success! It is really
>>> # only useful if you configure internal batching using linger_ms
>>> producer.flush()
>>> # Use a key for hashed-partitioning
>>> producer.send('foobar', key=b'foo', value=b'bar')
>>> # Serialize json messages
>>> import json
>>> producer = KafkaProducer(value_serializer=lambda v: json.dumps(v).encode('utf-8'))
>>> producer.send('fizzbuzz', {'foo': 'bar'})
>>> # Serialize string keys
>>> producer = KafkaProducer(key_serializer=str.encode)
>>> producer.send('flipflap', key='ping', value=b'1234')
>>> # Compress messages
>>> producer = KafkaProducer(compression_type='gzip')
>>> for i in range(1000):
...     producer.send('foobar', b'msg %d' % i)

Compression

kafka-python supports gzip compression/decompression natively. To produce or consume lz4 compressed messages, you must install lz4tools and xxhash (modules may not work on python2.6). To enable snappy compression/decompression install python-snappy (also requires snappy library).

Protocol

A secondary goal of kafka-python is to provide an easy-to-use protocol layer for interacting with kafka brokers via the python repl. This is useful for testing, probing, and general experimentation. The protocol support is leveraged to enable a KafkaClient.check_version() method that probes a kafka broker and attempts to identify which version it is running (0.8.0 to 0.10).

Usage

SimpleProducer

from kafka import SimpleProducer, KafkaClient

# To send messages synchronously
kafka = KafkaClient('localhost:9092')
producer = SimpleProducer(kafka)

# Note that the application is responsible for encoding messages to type bytes
producer.send_messages(b'my-topic', b'some message')
producer.send_messages(b'my-topic', b'this method', b'is variadic')

# Send unicode message
producer.send_messages(b'my-topic', u'你怎么样?'.encode('utf-8'))

Asynchronous Mode

# To send messages asynchronously
producer = SimpleProducer(kafka, async=True)
producer.send_messages(b'my-topic', b'async message')

# To wait for acknowledgements
# ACK_AFTER_LOCAL_WRITE : server will wait till the data is written to
#                         a local log before sending response
# ACK_AFTER_CLUSTER_COMMIT : server will block until the message is committed
#                            by all in sync replicas before sending a response
producer = SimpleProducer(kafka, async=False,
                          req_acks=SimpleProducer.ACK_AFTER_LOCAL_WRITE,
                          ack_timeout=2000,
                          sync_fail_on_error=False)

responses = producer.send_messages(b'my-topic', b'another message')
for r in responses:
    logging.info(r.offset)

# To send messages in batch. You can use any of the available
# producers for doing this. The following producer will collect
# messages in batch and send them to Kafka after 20 messages are
# collected or every 60 seconds
# Notes:
# * If the producer dies before the messages are sent, there will be losses
# * Call producer.stop() to send the messages and cleanup
producer = SimpleProducer(kafka, async=True,
                          batch_send_every_n=20,
                          batch_send_every_t=60)

Keyed messages

from kafka import (
    KafkaClient, KeyedProducer,
    Murmur2Partitioner, RoundRobinPartitioner)

kafka = KafkaClient('localhost:9092')

# HashedPartitioner is default (currently uses python hash())
producer = KeyedProducer(kafka)
producer.send_messages(b'my-topic', b'key1', b'some message')
producer.send_messages(b'my-topic', b'key2', b'this methode')

# Murmur2Partitioner attempts to mirror the java client hashing
producer = KeyedProducer(kafka, partitioner=Murmur2Partitioner)

# Or just produce round-robin (or just use SimpleProducer)
producer = KeyedProducer(kafka, partitioner=RoundRobinPartitioner)

KafkaConsumer

from kafka import KafkaConsumer

# To consume messages
consumer = KafkaConsumer('my-topic',
                         group_id='my_group',
                         bootstrap_servers=['localhost:9092'])
for message in consumer:
    # message value is raw byte string -- decode if necessary!
    # e.g., for unicode: `message.value.decode('utf-8')`
    print("%s:%d:%d: key=%s value=%s" % (message.topic, message.partition,
                                         message.offset, message.key,
                                         message.value))
messages (m) are namedtuples with attributes:
  • m.topic: topic name (str)
  • m.partition: partition number (int)
  • m.offset: message offset on topic-partition log (int)
  • m.key: key (bytes - can be None)
  • m.value: message (output of deserializer_class - default is raw bytes)
  from kafka import KafkaConsumer

  # more advanced consumer -- multiple topics w/ auto commit offset
  # management
  consumer = KafkaConsumer('topic1', 'topic2',
                           bootstrap_servers=['localhost:9092'],
                           group_id='my_consumer_group',
                           auto_commit_enable=True,
                           auto_commit_interval_ms=30 * 1000,
                           auto_offset_reset='smallest')

  # Infinite iteration
  for m in consumer:
    do_some_work(m)

    # Mark this message as fully consumed
    # so it can be included in the next commit
    #
    # **messages that are not marked w/ task_done currently do not commit!
    consumer.task_done(m)

  # If auto_commit_enable is False, remember to commit() periodically
  consumer.commit()

  # Batch process interface
  while True:
    for m in kafka.fetch_messages():
      process_message(m)
      consumer.task_done(m)


Configuration settings can be passed to constructor,
otherwise defaults will be used:
    client_id='kafka.consumer.kafka',
    group_id=None,
    fetch_message_max_bytes=1024*1024,
    fetch_min_bytes=1,
    fetch_wait_max_ms=100,
    refresh_leader_backoff_ms=200,
    bootstrap_servers=[],
    socket_timeout_ms=30*1000,
    auto_offset_reset='largest',
    deserializer_class=lambda msg: msg,
    auto_commit_enable=False,
    auto_commit_interval_ms=60 * 1000,
    consumer_timeout_ms=-1

Configuration parameters are described in more detail at
http://kafka.apache.org/documentation.html#highlevelconsumerapi

Multiprocess consumer

from kafka import KafkaClient, MultiProcessConsumer

kafka = KafkaClient('localhost:9092')

# This will split the number of partitions among two processes
consumer = MultiProcessConsumer(kafka, b'my-group', b'my-topic', num_procs=2)

# This will spawn processes such that each handles 2 partitions max
consumer = MultiProcessConsumer(kafka, b'my-group', b'my-topic',
                                partitions_per_proc=2)

for message in consumer:
    print(message)

for message in consumer.get_messages(count=5, block=True, timeout=4):
    print(message)

Low level

from kafka import KafkaClient, create_message
from kafka.protocol import KafkaProtocol
from kafka.common import ProduceRequest

kafka = KafkaClient('localhost:9092')

req = ProduceRequest(topic=b'my-topic', partition=1,
    messages=[create_message(b'some message')])
resps = kafka.send_produce_request(payloads=[req], fail_on_error=True)
kafka.close()

resps[0].topic      # b'my-topic'
resps[0].partition  # 1
resps[0].error      # 0 (hopefully)
resps[0].offset     # offset of the first message sent in this request

Intro to Kafka

18:16 Posted by SRE Hacks , , , , , , No comments

Introduction

Apache Kafk is a distributed streaming platform. What exactly does that mean?

We think of a streaming platform as having three key capabilities:
  1. It lets you publish and subscribe to streams of records. In this respect it is similar to a message queue or enterprise messaging system.
  2. It lets you store streams of records in a fault-tolerant way.
  3. It lets you process streams of records as they occur.
What is Kafka good for?
It gets used for two broad classes of application:
  1. Building real-time streaming data pipelines that reliably get data between systems or applications
  2. Building real-time streaming applications that transform or react to the streams of data
To understand how Kafka does these things, let's dive in and explore Kafka's capabilities from the bottom up.
First a few concepts:
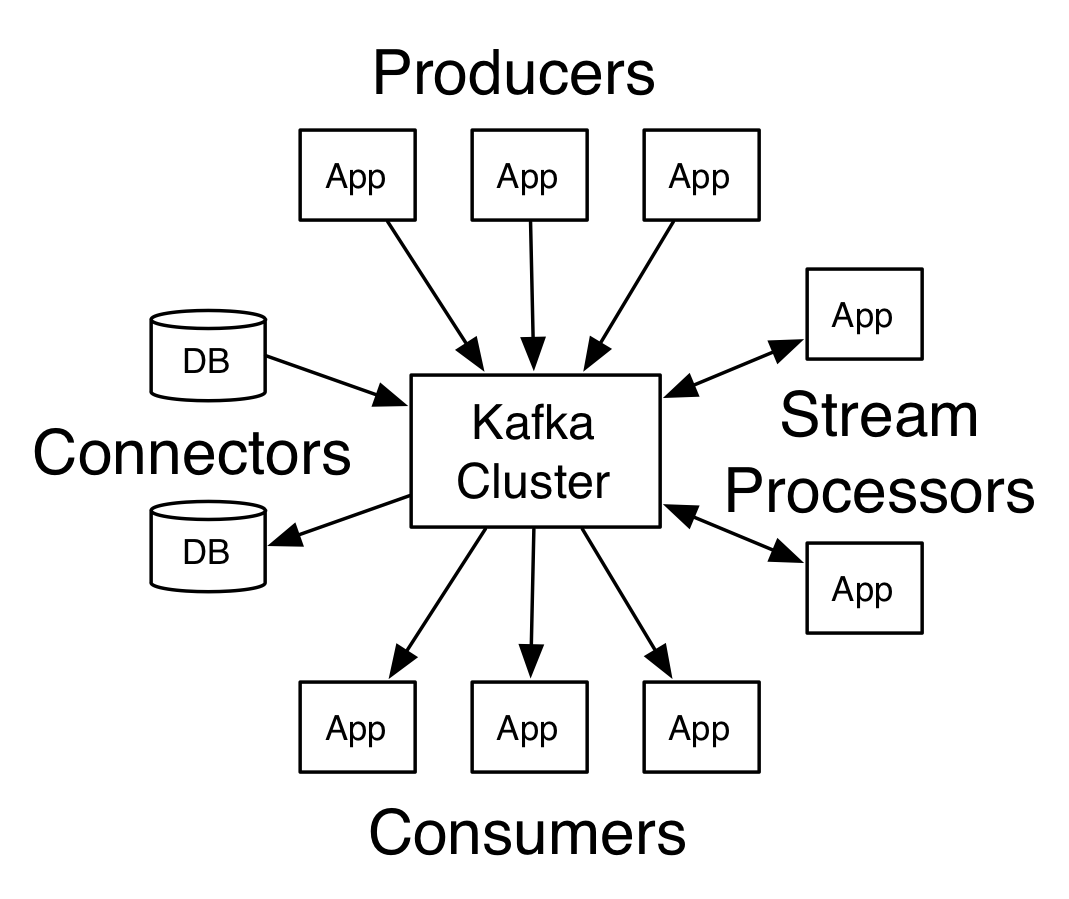
  • Kafka is run as a cluster on one or more servers.
  • The Kafka cluster stores streams of records in categories called topics.
  • Each record consists of a key, a value, and a timestamp.
Kafka has four core APIs:
  • The Producer API allows an application to publish a stream of records to one or more Kafka topics.
  • The Consumer API allows an application to subscribe to one or more topics and process the stream of records produced to them.
  • The Streams API allows an application to act as a stream processor, consuming an input stream from one or more topics and producing an output stream to one or more output topics, effectively transforming the input streams to output streams.
  • The Connector API allows building and running reusable producers or consumers that connect Kafka topics to existing applications or data systems. For example, a connector to a relational database might capture every change to a table.
In Kafka the communication between the clients and the servers is done with a simple, high-performance, language agnostic TCP protocol. This protocol is versioned and maintains backwards compatibility with older version. We provide a Java client for Kafka, but clients are available in many languages.

Topics and Logs

Let's first dive into the core abstraction Kafka provides for a stream of records—the topic.
A topic is a category or feed name to which records are published. Topics in Kafka are always multi-subscriber; that is, a topic can have zero, one, or many consumers that subscribe to the data written to it.
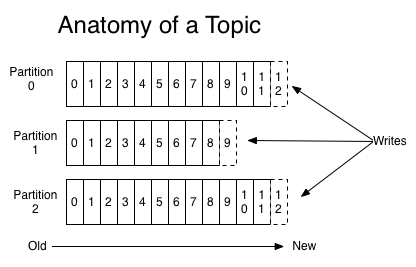
For each topic, the Kafka cluster maintains a partitioned log that looks like this:
Each partition is an ordered, immutable sequence of records that is continually appended to—a structured commit log. The records in the partitions are each assigned a sequential id number called the offset that uniquely identifies each record within the partition.
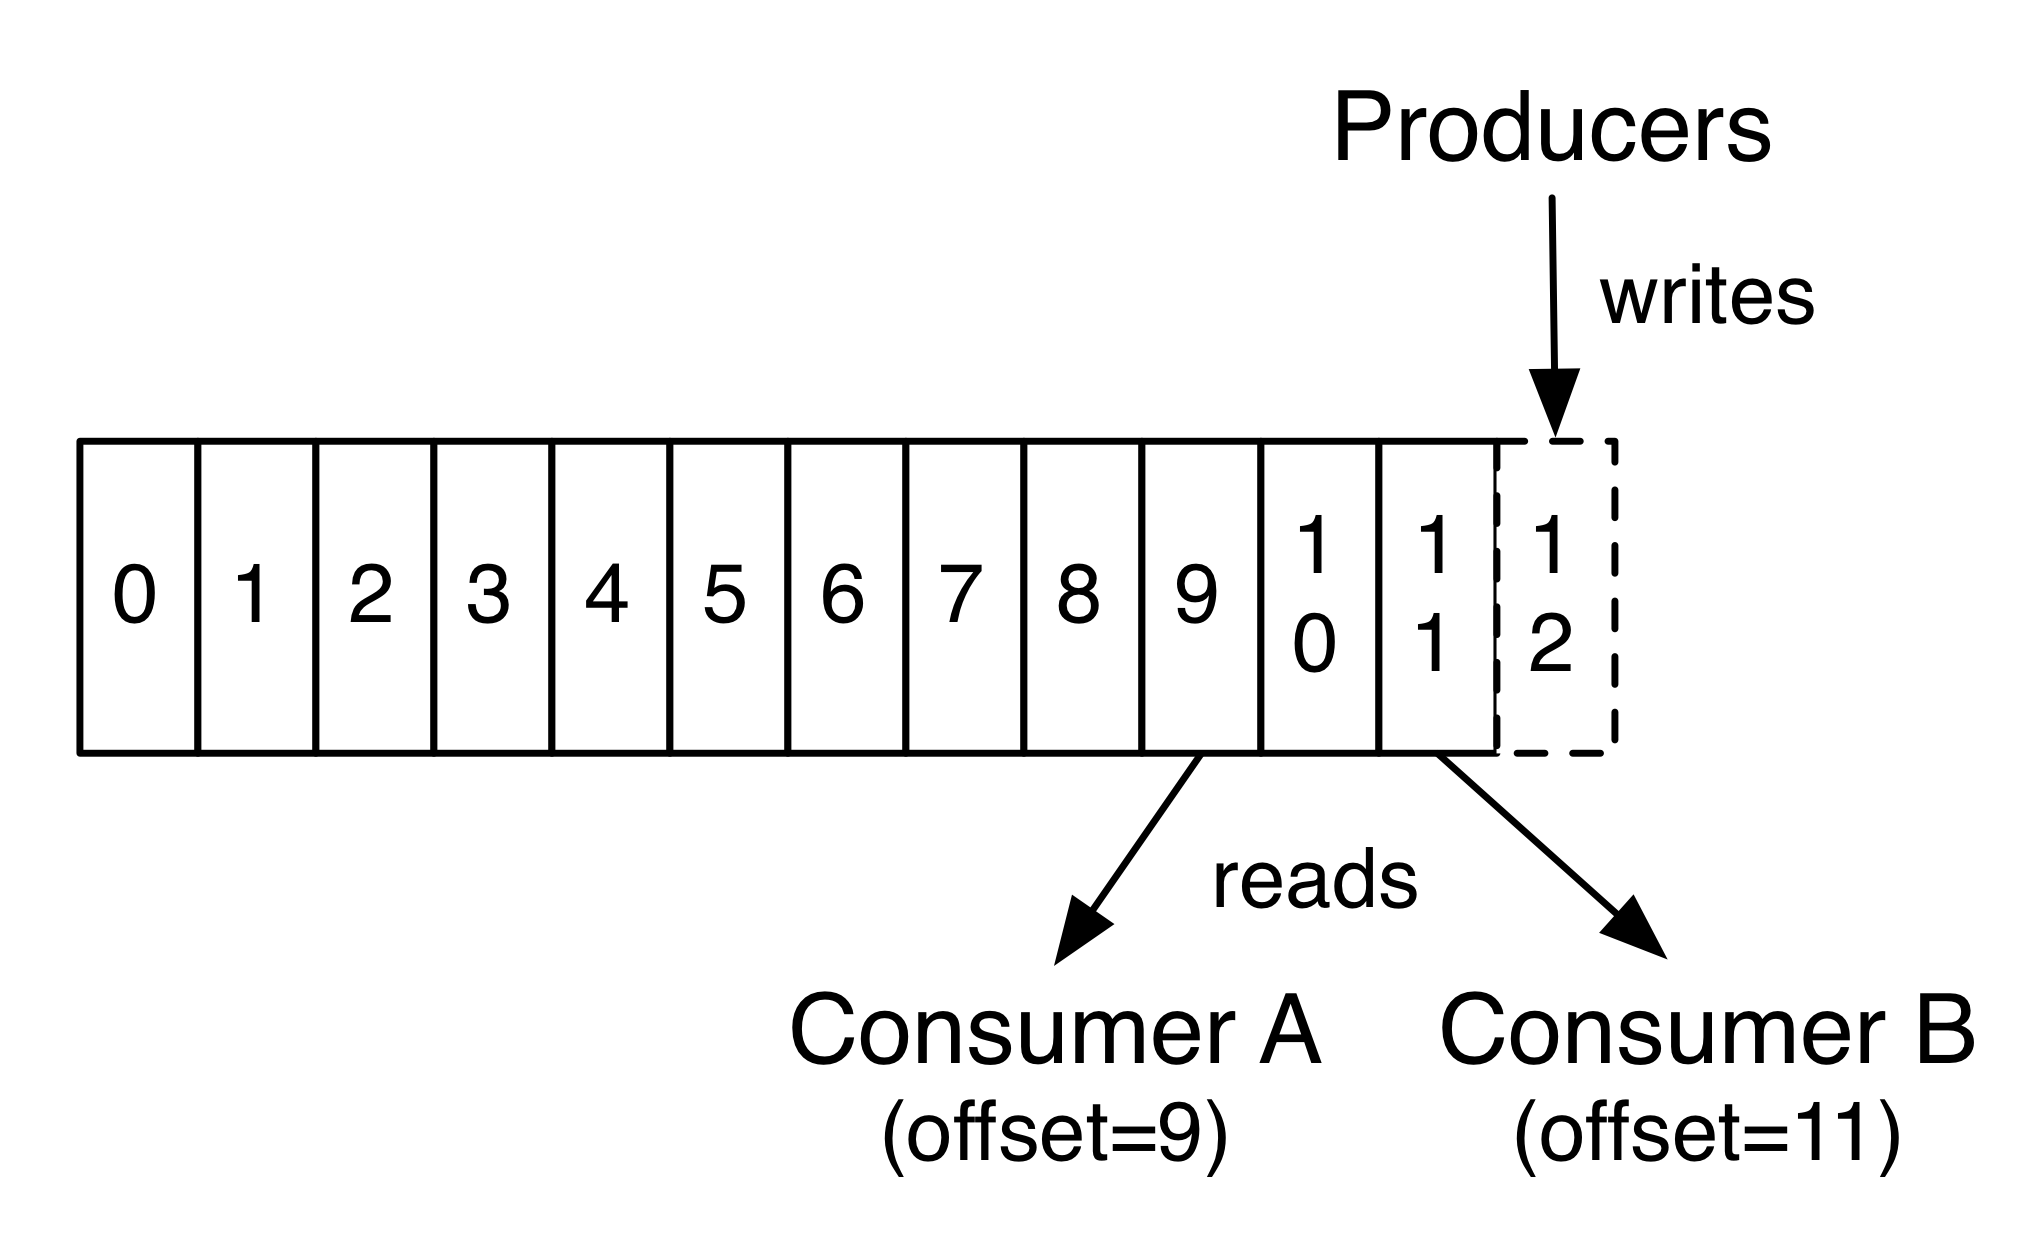
The Kafka cluster retains all published records—whether or not they have been consumed—using a configurable retention period. For example, if the retention policy is set to two days, then for the two days after a record is published, it is available for consumption, after which it will be discarded to free up space. Kafka's performance is effectively constant with respect to data size so storing data for a long time is not a problem.
In fact, the only metadata retained on a per-consumer basis is the offset or position of that consumer in the log. This offset is controlled by the consumer: normally a consumer will advance its offset linearly as it reads records, but, in fact, since the position is controlled by the consumer it can consume records in any order it likes. For example a consumer can reset to an older offset to reprocess data from the past or skip ahead to the most recent record and start consuming from "now".
This combination of features means that Kafka consumers are very cheap—they can come and go without much impact on the cluster or on other consumers. For example, you can use our command line tools to "tail" the contents of any topic without changing what is consumed by any existing consumers.
The partitions in the log serve several purposes. First, they allow the log to scale beyond a size that will fit on a single server. Each individual partition must fit on the servers that host it, but a topic may have many partitions so it can handle an arbitrary amount of data. Second they act as the unit of parallelism—more on that in a bit.

Distribution

The partitions of the log are distributed over the servers in the Kafka cluster with each server handling data and requests for a share of the partitions. Each partition is replicated across a configurable number of servers for fault tolerance.
Each partition has one server which acts as the "leader" and zero or more servers which act as "followers". The leader handles all read and write requests for the partition while the followers passively replicate the leader. If the leader fails, one of the followers will automatically become the new leader. Each server acts as a leader for some of its partitions and a follower for others so load is well balanced within the cluster.

Producers

Producers publish data to the topics of their choice. The producer is responsible for choosing which record to assign to which partition within the topic. This can be done in a round-robin fashion simply to balance load or it can be done according to some semantic partition function (say based on some key in the record). More on the use of partitioning in a second!

Consumers

Consumers label themselves with a consumer group name, and each record published to a topic is delivered to one consumer instance within each subscribing consumer group. Consumer instances can be in separate processes or on separate machines.
If all the consumer instances have the same consumer group, then the records will effectively be load balanced over the consumer instances.
If all the consumer instances have different consumer groups, then each record will be broadcast to all the consumer processes.
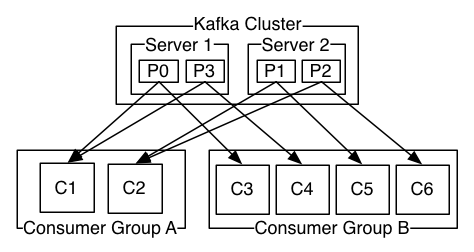
A two server Kafka cluster hosting four partitions (P0-P3) with two consumer groups. Consumer group A has two consumer instances and group B has four.
More commonly, however, we have found that topics have a small number of consumer groups, one for each "logical subscriber". Each group is composed of many consumer instances for scalability and fault tolerance. This is nothing more than publish-subscribe semantics where the subscriber is a cluster of consumers instead of a single process.
The way consumption is implemented in Kafka is by dividing up the partitions in the log over the consumer instances so that each instance is the exclusive consumer of a "fair share" of partitions at any point in time. This process of maintaining membership in the group is handled by the Kafka protocol dynamically. If new instances join the group they will take over some partitions from other members of the group; if an instance dies, its partitions will be distributed to the remaining instances.
Kafka only provides a total order over records within a partition, not between different partitions in a topic. Per-partition ordering combined with the ability to partition data by key is sufficient for most applications. However, if you require a total order over records this can be achieved with a topic that has only one partition, though this will mean only one consumer process per consumer group.

Guarantees

At a high-level Kafka gives the following guarantees:
  • Messages sent by a producer to a particular topic partition will be appended in the order they are sent. That is, if a record M1 is sent by the same producer as a record M2, and M1 is sent first, then M1 will have a lower offset than M2 and appear earlier in the log.
  • A consumer instance sees records in the order they are stored in the log.
  • For a topic with replication factor N, we will tolerate up to N-1 server failures without losing any records committed to the log.
More details on these guarantees are given in the design section of the documentation.

Kafka as a Messaging System

How does Kafka's notion of streams compare to a traditional enterprise messaging system?
Messaging traditionally has two models: queuing and publish-subscribe. In a queue, a pool of consumers may read from a server and each record goes to one of them; in publish-subscribe the record is broadcast to all consumers. Each of these two models has a strength and a weakness. The strength of queuing is that it allows you to divide up the processing of data over multiple consumer instances, which lets you scale your processing. Unfortunately, queues aren't multi-subscriber—once one process reads the data it's gone. Publish-subscribe allows you broadcast data to multiple processes, but has no way of scaling processing since every message goes to every subscriber.
The consumer group concept in Kafka generalizes these two concepts. As with a queue the consumer group allows you to divide up processing over a collection of processes (the members of the consumer group). As with publish-subscribe, Kafka allows you to broadcast messages to multiple consumer groups.
The advantage of Kafka's model is that every topic has both these properties—it can scale processing and is also multi-subscriber—there is no need to choose one or the other.
Kafka has stronger ordering guarantees than a traditional messaging system, too.
A traditional queue retains records in-order on the server, and if multiple consumers consume from the queue then the server hands out records in the order they are stored. However, although the server hands out records in order, the records are delivered asynchronously to consumers, so they may arrive out of order on different consumers. This effectively means the ordering of the records is lost in the presence of parallel consumption. Messaging systems often work around this by having a notion of "exclusive consumer" that allows only one process to consume from a queue, but of course this means that there is no parallelism in processing.
Kafka does it better. By having a notion of parallelism—the partition—within the topics, Kafka is able to provide both ordering guarantees and load balancing over a pool of consumer processes. This is achieved by assigning the partitions in the topic to the consumers in the consumer group so that each partition is consumed by exactly one consumer in the group. By doing this we ensure that the consumer is the only reader of that partition and consumes the data in order. Since there are many partitions this still balances the load over many consumer instances. Note however that there cannot be more consumer instances in a consumer group than partitions.

Kafka as a Storage System

Any message queue that allows publishing messages decoupled from consuming them is effectively acting as a storage system for the in-flight messages. What is different about Kafka is that it is a very good storage system.
Data written to Kafka is written to disk and replicated for fault-tolerance. Kafka allows producers to wait on acknowledgement so that a write isn't considered complete until it is fully replicated and guaranteed to persist even if the server written to fails.
The disk structures Kafka uses scale well—Kafka will perform the same whether you have 50 KB or 50 TB of persistent data on the server.
As a result of taking storage seriously and allowing the clients to control their read position, you can think of Kafka as a kind of special purpose distributed filesystem dedicated to high-performance, low-latency commit log storage, replication, and propagation.

Kafka for Stream Processing

It isn't enough to just read, write, and store streams of data, the purpose is to enable real-time processing of streams.
In Kafka a stream processor is anything that takes continual streams of data from input topics, performs some processing on this input, and produces continual streams of data to output topics.
For example, a retail application might take in input streams of sales and shipments, and output a stream of reorders and price adjustments computed off this data.
It is possible to do simple processing directly using the producer and consumer APIs. However for more complex transformations Kafka provides a fully integrated Streams API. This allows building applications that do non-trivial processing that compute aggregations off of streams or join streams together.
This facility helps solve the hard problems this type of application faces: handling out-of-order data, reprocessing input as code changes, performing stateful computations, etc.
The streams API builds on the core primitives Kafka provides: it uses the producer and consumer APIs for input, uses Kafka for stateful storage, and uses the same group mechanism for fault tolerance among the stream processor instances.

Putting the Pieces Together

This combination of messaging, storage, and stream processing may seem unusual but it is essential to Kafka's role as a streaming platform.
A distributed file system like HDFS allows storing static files for batch processing. Effectively a system like this allows storing and processing historical data from the past.
A traditional enterprise messaging system allows processing future messages that will arrive after you subscribe. Applications built in this way process future data as it arrives.
Kafka combines both of these capabilities, and the combination is critical both for Kafka usage as a platform for streaming applications as well as for streaming data pipelines.
By combining storage and low-latency subscriptions, streaming applications can treat both past and future data the same way. That is a single application can process historical, stored data but rather than ending when it reaches the last record it can keep processing as future data arrives. This is a generalized notion of stream processing that subsumes batch processing as well as message-driven applications.
Likewise for streaming data pipelines the combination of subscription to real-time events make it possible to use Kafka for very low-latency pipelines; but the ability to store data reliably make it possible to use it for critical data where the delivery of data must be guaranteed or for integration with offline systems that load data only periodically or may go down for extended periods of time for maintenance. The stream processing facilities make it possible to transform data as it arrives.
For more information on the guarantees, apis, and capabilities Kafka provides see the rest of the documentation.

My next blog is about how we use Kafka using python.
Subscribe my blog for further interesting blogs